Jul 23, 2017 11:51 AM
(This post was last modified: Jul 23, 2017 12:01 PM by movsx.)
Introduction
Part 2 of this tutorial is about parsing and use of syntax directed translation to convert our parse tree into an abstract syntax tree. In parsing, we take a sequence of tokens from the lexer stage and use it to build a parse tree. Not only that, but we have to confirm that the input forms a valid grammar for the language (we will discuss semantic analysis in later tutorials).
So, last tutorial, we ran our input through a lexer. It then broke this input into tokens. Say we want to lex the math expression:
"1 + 3132 1337" This is a character string of length 15
A lexer would spit out {NUMBER, +, NUMBER, *, NUMBER}, an array of size 5. It's also classified 1, 3132, and 1337 as "NUMBER" Now our job as a parser is easy, because we've broken down the input into something smaller. Now we feed this input into the parser to generate a parse tree.
The idea behind parsing is we define our language grammar in terms of a context free grammar. However, we need to do a bit more than that, because C isn't a context free grammar, it actually depends on context. For example, let's look at the following C code:
Is it an expression or is it a declaration? We can't determine this from the context alone. It is an expression if Token is an identifier. If Token is a type, then it's a declaration. We need a symbol table to answer this specific question (discussed in part 3). So to build a C parser, we use context free grammars in addition with some extra code thrown in to help us determine the difference between issues as discussed above.
Crash Course on Context-Free Grammars
Some definitions you'll want to understand:
Terminal symbols: Symbols which cannot be replaced.
Non-terminal symbols: Symbols which can be replaced.
To break this down even more, let's say a "terminal symbol" is a token that comes out of our lexer. A "nonterminal symbol" is a group of tokens in our parser. Production rules are also non-terminal symbols.
A production rule is a rule which tells us we can take a group of nonterminal and terminal symbols and replace them with this specific nonterminal. I.e.,
E -> NUMBER + NUMBER
This production rule says that if we see NUMBER + NUMBER in our input, we can replace that with E. So how do we parse something? Simple. We have a start derivation rule and collection of derivation rules. In a top-down parser, our goal is to go from the start derivation rule and apply derivation rules until we match the input sequence. There's also a special symbol called "epsilon" which means the empty token. I.e., we can use this derivation to match essentially nothing.
As an example, suppose we have this grammar, with the start derivation rule beng "S" (NOTE the pipe "|" is a special character which means "OR". It means E derives E + E OR E E OR the terminal number.
S -> E
E -> E + E | E E | number
Now say we have the input "1 + 1 2"
We have a tuple that represents our current state. So (S, "") represents we've started from the start symbol, and "" represents our current match.
(1) (S -> E, "E")
(2) (E -> E + E, "E + E")
(3) (E -> E E, "E + E E")
(4) (E -> number, "number + E E")
(5) (E -> number, "number + number E")
(6) (E -> number, "number + number number")
As you can see, we've also generated our parse tree while doing this. The parse tree is essentially the rules we've applied to go from the start symbol to the matching output!
!!!!!! In step (2) what happens if we applied E -> E E instead of E -> E + E? Then our parse tree would change the expression from 1 + 1 2 to (1 + 1) 2. This is very bad. We address this later in this tutorial.
But there are FOUR things to notice:
(1) We've applied our rules and replacements from LEFT to RIGHT.
(2) There are multiple derivations we can use to reach the same output! (Try the above on 1 + 2 + 3 by yourself) This is BAD as it means our grammar is ambiguous! We need to write an unambiguous grammar.
(3) How to handle operator precedence? (Discussed later)
(4) This grammar is LEFT RECURSIVE. Look at E -> E + E. It means essentially the leftmost symbol in its production is itself. I've highlighted this symbol in red. This will cause problems in recursive descent parsers.
LL(1) Grammars
LL(1) grammars mean we can scan the input from left to right, deriving the parse tree from top-bottom and using at most 1 lookahead symbol at the same time. This introduces a problem. We cannot use recursive descent parsers to parse left recursive grammars. Say we have the grammar from above:
S -> E
E-> E + E | E E | number
How we would implement this in a recursive descent parser, is we'd have a function for each production rule. For instance, in pseudocode
So above we can see the issue is E calls itself without consuming any input. Oh oh. This will cause a stack overflow. We can fix this issue by converting our left recursive grammar into a right recursive one. There's also another issue we need to fix: precedence. We do this by wrapping lower precedence production rules at "higher" levels than higher precedence production rules.
So above, to fix precedence:
S -> E
E -> E + E | E E | number
We convert this into
S -> E
E -> E + T | T
T -> T number | number
But we still have a problem. This grammar is left recursive. Think hard about this. You'll note that the below grammar is equivalent AND right recursive.
S -> E
E -> T + E | T
T -> number T | number
CFG for a subset of C
parser.h contains the CFG for a subset of C. Read my comments in the parser.h code, it explains the issue in more detail. It also discuss the dangling else problem, and how the top down parser automatically solves this issue.
The dangling else problem is this: In the following code, which "IF" does the "ELSE" belong to? Line 1 or 2? (It is line 2, but as you'll note, depedning on our grammar, it is ambiguous, this causes problems, but we can fix it in our actual parser, without modifying the grammar (both solutions work fine, though))
parser.h
https://pastebin.com/C3dsqYpS
Syntax Directed Translation
We want to directly output an abstract syntax tree from our recursive descent parser. Not a parse tree. So we use syntax directed translation to do this. I won't discuss the theory, it can span multiple CS/EE courses. But I'll tell you what it does, and you can see from my code how it works.
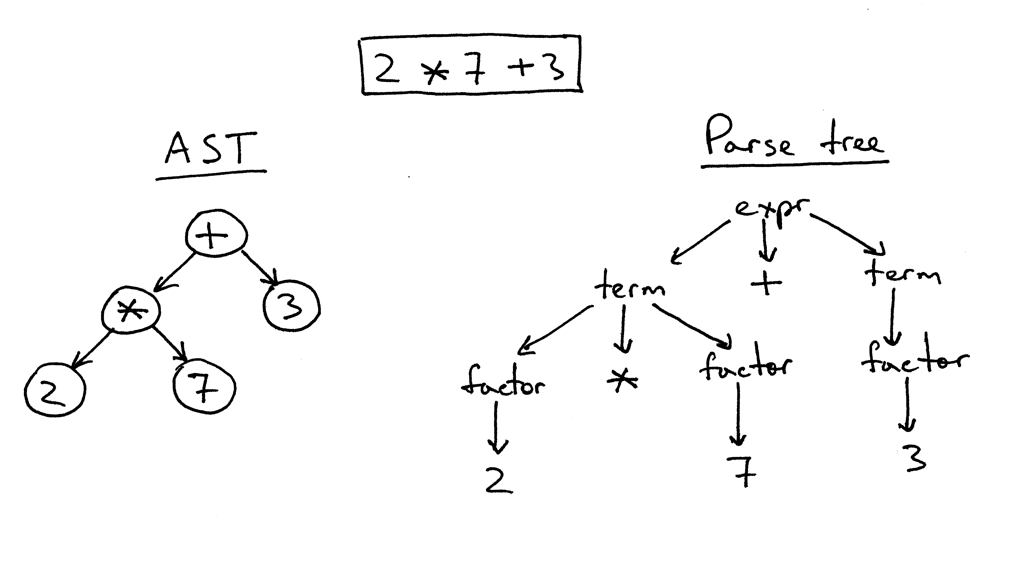
Parse trees are ugly as fuck and hard to work with. Just imagine how ugly it'd be for an even larger input. We want to make it pretty and transform the right tree into the left one.
We define a struct for our AST node to make it convenient to work with. Now might be a good time to look into unions if you're not familiar with them.
astnode.h
https://pastebin.com/xEqu0mTU
And now, here's the code for the recursive descent parser. Read the comments, they offer some light. And take note to comments about error checking. Also specifically look into backtracking. What is backtracking? Our parser has to backtrack. Why? This isnt covered in the tutorial, I expect you to figure it out, and perhaps talk about it in the comments. Look at my code. See how I backtrack.
parser.c
https://pastebin.com/cfyESE4B
Here's an example input:
Our lexer spits out:
Our parser spits out an AST:
Next Tutorial
The next tutorial will be posted next weekend, when I have more time. My last tutorial got a lot of hate. If people are going to hate on my tutorials, and expect them to be something they can just copy paste into their own projects, without any effort whatsoever to learn the topic at hand then there won't be a third. I've already written the metamorphic engine. This tutorial took me 2 hours to write. Time is valuable, and I won't spend it where it's not appreciated.
Part 2 of this tutorial is about parsing and use of syntax directed translation to convert our parse tree into an abstract syntax tree. In parsing, we take a sequence of tokens from the lexer stage and use it to build a parse tree. Not only that, but we have to confirm that the input forms a valid grammar for the language (we will discuss semantic analysis in later tutorials).
So, last tutorial, we ran our input through a lexer. It then broke this input into tokens. Say we want to lex the math expression:
"1 + 3132 1337" This is a character string of length 15
A lexer would spit out {NUMBER, +, NUMBER, *, NUMBER}, an array of size 5. It's also classified 1, 3132, and 1337 as "NUMBER" Now our job as a parser is easy, because we've broken down the input into something smaller. Now we feed this input into the parser to generate a parse tree.
The idea behind parsing is we define our language grammar in terms of a context free grammar. However, we need to do a bit more than that, because C isn't a context free grammar, it actually depends on context. For example, let's look at the following C code:
Code
Token * A;Is it an expression or is it a declaration? We can't determine this from the context alone. It is an expression if Token is an identifier. If Token is a type, then it's a declaration. We need a symbol table to answer this specific question (discussed in part 3). So to build a C parser, we use context free grammars in addition with some extra code thrown in to help us determine the difference between issues as discussed above.
Crash Course on Context-Free Grammars
Some definitions you'll want to understand:
Terminal symbols: Symbols which cannot be replaced.
Non-terminal symbols: Symbols which can be replaced.
To break this down even more, let's say a "terminal symbol" is a token that comes out of our lexer. A "nonterminal symbol" is a group of tokens in our parser. Production rules are also non-terminal symbols.
A production rule is a rule which tells us we can take a group of nonterminal and terminal symbols and replace them with this specific nonterminal. I.e.,
E -> NUMBER + NUMBER
This production rule says that if we see NUMBER + NUMBER in our input, we can replace that with E. So how do we parse something? Simple. We have a start derivation rule and collection of derivation rules. In a top-down parser, our goal is to go from the start derivation rule and apply derivation rules until we match the input sequence. There's also a special symbol called "epsilon" which means the empty token. I.e., we can use this derivation to match essentially nothing.
As an example, suppose we have this grammar, with the start derivation rule beng "S" (NOTE the pipe "|" is a special character which means "OR". It means E derives E + E OR E E OR the terminal number.
S -> E
E -> E + E | E E | number
Now say we have the input "1 + 1 2"
We have a tuple that represents our current state. So (S, "") represents we've started from the start symbol, and "" represents our current match.
(1) (S -> E, "E")
(2) (E -> E + E, "E + E")
(3) (E -> E E, "E + E E")
(4) (E -> number, "number + E E")
(5) (E -> number, "number + number E")
(6) (E -> number, "number + number number")
As you can see, we've also generated our parse tree while doing this. The parse tree is essentially the rules we've applied to go from the start symbol to the matching output!
!!!!!! In step (2) what happens if we applied E -> E E instead of E -> E + E? Then our parse tree would change the expression from 1 + 1 2 to (1 + 1) 2. This is very bad. We address this later in this tutorial.
But there are FOUR things to notice:
(1) We've applied our rules and replacements from LEFT to RIGHT.
(2) There are multiple derivations we can use to reach the same output! (Try the above on 1 + 2 + 3 by yourself) This is BAD as it means our grammar is ambiguous! We need to write an unambiguous grammar.
(3) How to handle operator precedence? (Discussed later)
(4) This grammar is LEFT RECURSIVE. Look at E -> E + E. It means essentially the leftmost symbol in its production is itself. I've highlighted this symbol in red. This will cause problems in recursive descent parsers.
LL(1) Grammars
LL(1) grammars mean we can scan the input from left to right, deriving the parse tree from top-bottom and using at most 1 lookahead symbol at the same time. This introduces a problem. We cannot use recursive descent parsers to parse left recursive grammars. Say we have the grammar from above:
S -> E
E-> E + E | E E | number
How we would implement this in a recursive descent parser, is we'd have a function for each production rule. For instance, in pseudocode
Code
bool E() {

    if (E() && '+' && E()) // BIG PROBLEM!!!

    .....

}
So above we can see the issue is E calls itself without consuming any input. Oh oh. This will cause a stack overflow. We can fix this issue by converting our left recursive grammar into a right recursive one. There's also another issue we need to fix: precedence. We do this by wrapping lower precedence production rules at "higher" levels than higher precedence production rules.
So above, to fix precedence:
S -> E
E -> E + E | E E | number
We convert this into
S -> E
E -> E + T | T
T -> T number | number
But we still have a problem. This grammar is left recursive. Think hard about this. You'll note that the below grammar is equivalent AND right recursive.
S -> E
E -> T + E | T
T -> number T | number
CFG for a subset of C
parser.h contains the CFG for a subset of C. Read my comments in the parser.h code, it explains the issue in more detail. It also discuss the dangling else problem, and how the top down parser automatically solves this issue.
The dangling else problem is this: In the following code, which "IF" does the "ELSE" belong to? Line 1 or 2? (It is line 2, but as you'll note, depedning on our grammar, it is ambiguous, this causes problems, but we can fix it in our actual parser, without modifying the grammar (both solutions work fine, though))
Code
1. if ()

2. if ()

3. else ...
parser.h
https://pastebin.com/C3dsqYpS
Syntax Directed Translation
We want to directly output an abstract syntax tree from our recursive descent parser. Not a parse tree. So we use syntax directed translation to do this. I won't discuss the theory, it can span multiple CS/EE courses. But I'll tell you what it does, and you can see from my code how it works.
Parse trees are ugly as fuck and hard to work with. Just imagine how ugly it'd be for an even larger input. We want to make it pretty and transform the right tree into the left one.
We define a struct for our AST node to make it convenient to work with. Now might be a good time to look into unions if you're not familiar with them.
astnode.h
https://pastebin.com/xEqu0mTU
And now, here's the code for the recursive descent parser. Read the comments, they offer some light. And take note to comments about error checking. Also specifically look into backtracking. What is backtracking? Our parser has to backtrack. Why? This isnt covered in the tutorial, I expect you to figure it out, and perhaps talk about it in the comments. Look at my code. See how I backtrack.
parser.c
https://pastebin.com/cfyESE4B
Here's an example input:
Code
{

    int x;

    x = 0;

    while (x < 10) {

        x = x + 1;

    }

}
Our lexer spits out:
Code
[{] [INT] [Identifier x] [;] [Identifier x] [=] [Int Literal=0] [;] [WHILE ] [(] [Identifier x] [<] [Int Literal=10] [)] [{] [Identifier x] [=] [Identifier x] [+] [Int Literal=1] [;] [}] [}]Our parser spits out an AST:
Code
BLOCK

    DECLARATIONS

        DECLARATIONS

        DECLARATION

            TYPE INT

            ID x

    STATEMENTS

        ASSIGN

            ID x

            LITERAL 0

        STATEMENTS

            WHILESTMT

                BINOP <

                    ID x

                    LITERAL 10

                BLOCK

                    DECLARATIONS

                    STATEMENTS

                        ASSIGN

                            ID x

                            BINOP +

                                ID x

                                LITERAL 1

                        STATEMENTS

            STATEMENTS
Next Tutorial
The next tutorial will be posted next weekend, when I have more time. My last tutorial got a lot of hate. If people are going to hate on my tutorials, and expect them to be something they can just copy paste into their own projects, without any effort whatsoever to learn the topic at hand then there won't be a third. I've already written the metamorphic engine. This tutorial took me 2 hours to write. Time is valuable, and I won't spend it where it's not appreciated.