


Dec 23, 2014 04:24 AM
(This post was last modified: Dec 23, 2014 04:34 AM by ~Dec.)
note: this document is a work in progress but was originally published here: https://gist.github.com/declandewet/6b8f...872a6e7227
Asynchronous JavaScript Programming
A Basic Primer
This document will cover the basic underlying principles of asynchronous programming in JavaScript, and how to manage asynchronous code more effectively.
Introduction
It is not fairly straightforward to jump straight in to asynchronous programming without first understanding how asynchronous code works.
What is asynchronous programming for?
In most programming languages, expensive operations "block the process", which means that any code that is interpreted after an expensive operation will have to wait for said operation to finish before running. An "expensive operation" could be anything from looking up a resource in a database, writing to a file, or fetching some data from an HTTP endpoint.
Here is a basic example in quasi-pseudocode, where we grab some user input, log 1, fetch an item from a database, log 2, log 3, and then show the user the result of the database fetch. Let's just assume that for the sake of this example, that the average time a line of code takes to execute is 1 second, and that our logs operate at that speed, and that we're using those log calls to count time in seconds (which is definitely not the right way to do it, but bare with me here).
If we had to actually run this code, we would expect (based on our assumption) that log(1) would run for a second, then the next line would run, and then log(2) would run while the previous line did it's thing and then log(3) would run for a second (making 3 seconds).
In actuality, the database operation could take any set number of seconds to operate, and log(2) would have to wait for this operation to finish executing before it will be run, making our timer incorrect.
If you've been paying attention, you might notice that the log calls have absolutely nothing to do with the database operation, and thus do not have to rely on it executing in order to function on their own, making the above code incredibly inefficient.
This is where asynchronous programming steps in to save the day.
Before we continue, please make note of the try/catch block, most notably the number of times we listen for an error (that's one time, in case you're hungover). Make a mental note of it, put it aside, and we'll come to why you just did that later.
How does asynchronous code work?
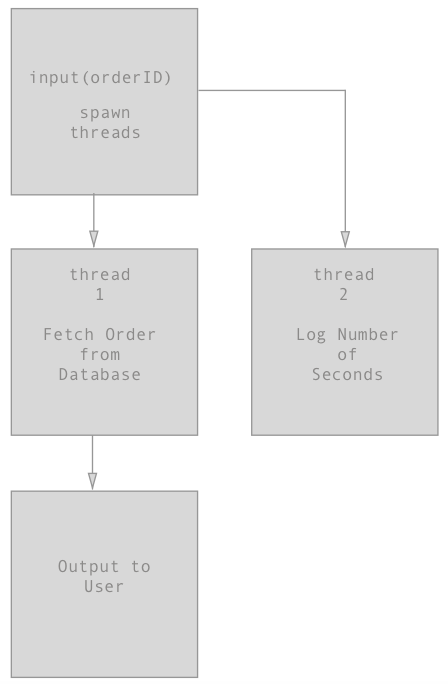
In the vast majority of programming languages, asynchronous code is run by the spawning of multiple threads. A program receives some input, and delegates one task to one thread, and another task to another thread, and so on, for a set number of tasks. These threads run these tasks in parallel, and when the thread finishes executing, the value is returned to the main thread. This is a process that is largely similar in concept to multithreading, but it's important to remember that multithreading and asynchronism are not the same thing. This diagram should help illustrate the flow of this process in the context of our order/timer example:
The difference between regular synchronous code and asynchronous code is best explained as a metaphor. Try to imagine that your program is a fancy bistro restaurant. The synchronous version of your restaurant would have one server behind a counter, who is able to serve one customer at a time. Customers would line up in single file, and have to wait for the orders to be processed, calculated and paid for before they can be received. An asynchronous restaurant would have waiters attending multiple customers at a time, the customer makes their order, the waiter adds the order to the system, while the order is being prepared the waiter will go ahead and service some other tables. It's kind of like saying to your program, "Please process these tasks for me - in the meantime I'm going to calculate Pi to the n^th dividend of Fibonacci after the first Prime Roman numeral - when you're done doing your thing, notify me of your findings."
This presents an issue in JavaScript, because JavaScript is not one of the vast majority of languages that runs on multiple threads - it is a single threaded language. So how do we handle asynchronous code in JavaScript?
How asynchronous code works in the context of JavaScript
Let me, for illustrative purposes, show you a function you might already know about:
If you've done much programming in JavaScript, you might know that this little guy runs whatever is inside that anonymous function body after a specified delay in milliseconds. However, there is something about him that is not very obvious at first glance. Have a look at this code, and try to guess the order in which the console.log statements occur:
If you guessed that the log statements would output 1, followed by 2, then you are wrong.
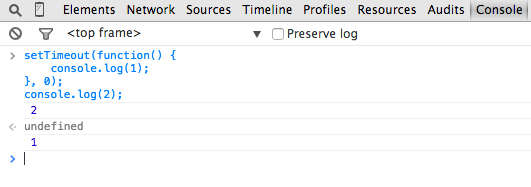
So, what's the deal here? Why is this program executing backwards? There's no delay - so it should run in order, right?
Wrong. Function calls cost execution time too, so the whole setTimeout operation was a little bit more costly in terms of processing time than the regular console.log, but that isn't really important - what is important is that the code that followed the setTimeout continued to execute regardless of whether or not the setTimeout was finished.
This is probably due to the native code behind the setTimeout being asynchronous to some degree, and knowing every exact detail of what occurs behind the scenes is not super important - but it gives us something to work with. We can leverage setTimeout to develop asynchronous methods.
Before we get started building an asynchronous method, it's important to first understand how asynchronous methods are consumed at the most basic level.
How to consume asynchronous methods in JavaScript
There are three different basic styles. First off is the callback, errback approach - probably the most common and oldest of the three:
You call a function, and pass two functions as arguments to this function. The first function is the "callback", and the second function is the "errback". The callback receives the returned value of the function as a parameter, and is called with this value if no errors occur. If an error does occur, the errback is called instead of the callback, and it usually receives an error message or error object as a parameter.
Second is the success / fail object approach, which you might recognise from something like jQuery's $.ajax method:
This works almost the same way as the callback / errback approach, the difference being that the object's fail and success methods are called instead - but it does allow for a little more flexibility, for example the method might support more handlers that are called at different steps of execution, like an onProgress: function(percent) {} for a file upload.
The third approach, and probably the most prolific of the three, is the regular callback approach, made popular by Node.js:
In this approach, the callback is called with an error if one occurs. If not, the first argument is passed as null and the second argument is the resolved value of the method.
Please note that these callbacks may have more than just one parameter, and the most important quality of a callback is that it has access to the scope of the function that it is an argument of.
We'll focus on the third approach when building our asynchronous method.
Building an asynchronous method in JavaScript
Let's use everything we've spoken about up until this point to build a little asynchronous method.
We'll be building a tiny little find method that finds a person in an in-memory database of persons. Our "in-memory database" will simply be an array of people:
Now, let's build an asynchronous method for finding a single person in this array by their name.
We know that our method should accept a name for finding the person, and a callback function that should be called with the found person, or an error if one occurs.
Let's get the basics in place first.
Inside this function, we should define another function, thereby creating a closure, that can be called in a setTimeout.
The final part of the basic structure is to actually call this inner function in a setTimeout. We'll give this a delay of 3 seconds to emulate an expensive database operation, just for the sake of example. In best practice, the delay should always be 0.
Right now, our code doesn't exactly do anything except call an empty function after a 3 second delay, so we'll implement the part that actually finds the person. Just to make it a little simple, we'll do this using functional programming methods. In EcmaScript 5, arrays have prototypical methods like map, forEach and some.
You're most likely already familiar with forEach if you're reading up on asynchronous programming patterns, but might not be familiar with some. some is exactly the same as forEach, with the tiny exception that it immediately stops iterating when it encounters a callback that returns true.
So, we will define a foundPerson flag as null at the outermost scope of our closure, and we will use this flag to detect if the user has been found when the iteration is complete. Before we focus on errors though, we will just implement the logic that iterates through the people array, returns true when a matching person is found, sets the foundPerson flag to the found person, then calls the callback with the found person.
Keep in mind that the first argument to callback is error, so we'll pass null for that if we've found a person.
Now we finally need to implement error handling - which is actually pretty simple. We just check to see if the foundPerson flag is still null, and if so, create an error and call the callback with the error.
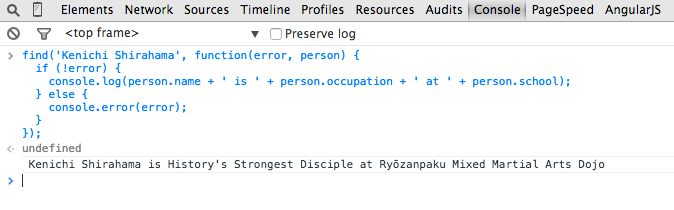
Phew, that was quite a bit of code for such a simple task. But now we can use this method to find a person by their name:
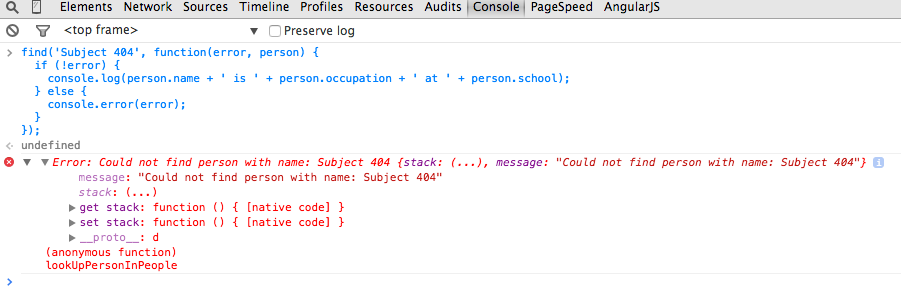
Let's try that again, but this time with a name that we know does not exist:
How to Be a Slave and Build your own Great Pyramids (or: callback hell and why it's a horrible place full of plague and famine)
If you're the type of person who can predict the future, you might have noticed that you might end up in a particularly bad situation with this code structure (well, that or you've realised you can use your psychic future seeing abilities to make money much easier than by programming and are probably fantasising about being on a cruise somewhere in the Caribbean).
If you're not that type of person, your future-seeing brethren definitely have reason to worry, and so should you.
What do you think will happen if you use many of these asynchronous methods in sequence? Let me illustrate by reading a directory of files, iterating through these filenames, reading in the files individually and uploading them to some random endpoint:
Now imagine you wanted to do other stuff with that response, like save it to a dictionary database of image paths to result URLs, and then produce a document of that dictionary and asynchronously send it to another API that prints the document from a fax machine somewhere in the Swiss Alps... you'd be getting in pretty deep, having to nest deeper with each method and check for that error all the time. It could become quite unsettling. The huge sideways pyramid of whitespace on the left created by all this nesting is called the pyramid of doom, and when you see it, it is the landmark that tells you that you are in callback hell. Be sure to send postcards, if you can find them.
Another issue with this, though not immediately obvious, are all the anonymous functions. If errors throw, you'll lose the execution context of those errors and your stack trace will be littered with <anonymous>.fn tokens. Identifying where your errors occur will be tough.
All of this combines and results in extremely unreadable, hard-to-understand code.
Luckily for your fortunate-unfortunate self, there is an escape route.
How to Escape Callback Hell
Use CoffeeScript. Just kidding. But this does raise a valid point, a lot of programmers new to the JS space think using a language like CoffeeScript might help solve the problem by reducing the amount needed to type because of the terse syntax it provides, kind of like a trade of some form of productivity for another form of productivity.
The reality of the matter is that using CoffeeScript does not directly solve the problem here. While it does add some benefit by removing some of the syntax, it doesn't exactly mitigate the need to constantly check for errors and it does not get rid of the need to nest, it also adds no benefit to that anonymous function issue - but it does get rid of half of that pyramid of doom, which is nice and all, but you're still left with half a pyramid of doom. Whether you have a whole turd or half a turd, it's still a turd, and you have it. Congratulations - here, have a Noddy badge. You deserve this for your achievement. Put it in your trophy room, right next to your shiny half-turd:
disclaimer: Possible bias. I'm actually rather fond of CoffeeScript. But it does not solve everything.
Getting Rid of Anonymous Functions
Here's something we can do without much thought that can help ease the debugging, and that's by giving our anonymous functions some identifiable names:
Hoisting to the Rescue!
The above code has one immediately obvious benefit to it's predecessor, and that is that it will now display actual function names rather than <anonymous>.fn tokens in the error stack. This makes debugging easier. But there is one other benefit that is not immediately obvious, and it comes into practice when we remember that JavaScript "hoists" function definitions to the top of the scope at execution time. We can define our functions outside of where they are called for some very readable code:
This gets rid of most of our issues by trading in just a little bit more verbosity. But we still have to check for errors in multiple places. Though this may not be perfect, it is at least readable and much easier to understand. Plus, there's no pyramid of doom. Yay!
We can improve this a little further and make errors a lot easier to handle.
All Hail The Mighty EventEmitter
In Node.js, asynchronous methods work a little differently under the hood than I explained above. You might have heard about the mysterious "event loop" that is behind every Node program. Pretty much everything in Node emits events behind the scenes that get queued in this loop, and some methods add listeners for certain events that call methods when those events emit. Which is kind of like what we did above, just a different, more systemised architecture.
(side note: Node.js also prefers setImmediate and nextTick as opposed to setTimeout, which work similarly)
We have access to the class that emits these events in Node, and we can use it to make our error handling a little easier. It's quite simple:
We haven't changed much, and we still have to check for errors in multiple places, but this is a big improvement, because if we want to do anything with those errors, we only have to do it in one place:
This code is still a little bit haphazard. Perhaps it might be worth representing as a singleton object that inherits from EventEmitter. While we're doing that, we might as well change up the API a little bit and make it easy to perform this logic on any directory of files. I'm not going to delve into the process here, so this is what that looks like:
Just for the sake of interest, here is what the exact same code looks like in CoffeeScript:
Now, we can use this little program to upload any directory we want, and handle errors rather easily:
Promises
Earlier, we created this really intrinsic constructor API for dealing with readable, asynchronous code that allowed you to handle errors in one place.
Now let me show you just how much of a waste of time that was with this snippet of code that does the exact same thing:
The when variable here is a reference to the when.js promise library, which gives us the when.map and node.call methods. when.map resolves an array of values or an array of promises for values. If any of these values throw an error, our error handler will catch it. when.map accepts a predicate function that has access to the resolved values in our array of promises returned by fs.readdir. node.call simply creates a promise for the result of a node-style callback. If any of the methods we promisified using node.call throw errors, those errors will bubble up to our error handler, where we can then handle them.
If you inspect the code closely, you might notice that this is modelled as closely to the try / catch block pattern as possible (well, to the extent that asynchronous JavaScript can provide, anyway).
I'm not going to delve too much into promises here, because there are plenty of tutorials and even a standardised specification called "Promises/A+" that you can learn from if you Google around for a bit.
The only thing you really need to know about promises for now is that they are just objects and can be passed around just as easily as any function. Well, that's the premise behind them anyway.
The specific name for a promise is a "deferred object" - a deferred object has three states: pending, resolved and rejected. When a promise is busy executing, it is pending. When a promise succeeds, it resolves with a value. If it fails, it rejects with an error. A promise will return a "thenable", which is another object that is essentially just a chainable API for accessing these resolved values or rejection errors, that always has a "then" method.
This is what a promise constructor might look like on top of our asynchronous find method from earlier:
The Future of Asynchronous JavaScript (is actually now)
In ES6, we can use promises in a much more descriptive manner that might make you smile if you are used to writing synchronous code, using generator functions:
You can use this method of asynchronous programming today by using an ES6-ES5 transpiler like Google's Traceur Compiler or just directly in the latest Node.js pre-release.
ES7 has plans for async/await keywords, which essentially just hides promises behind the scenes. So things are definitely looking up for JavaScript.
Ending note:
I know I never covered promises as thoroughly as one might expect from such an article, but in truth they are quite complex to understand to a beginner, and I am not 100% confident in my ability to teach them as a concept without making mistakes. If you do not understand promises, do not be alarmed - we all went through this at some stage. The best way to improve your promise skills is simply to just dive in and code something with them. Perhaps starting with an easier library like Q.js might be worth a try. On that note, there are hundreds of articles that will teach you about promises - just be sure to make certain that the promise implementation you are using is Promises/A+ compliant.
Asynchronous JavaScript Programming
A Basic Primer
This document will cover the basic underlying principles of asynchronous programming in JavaScript, and how to manage asynchronous code more effectively.
Introduction
It is not fairly straightforward to jump straight in to asynchronous programming without first understanding how asynchronous code works.
What is asynchronous programming for?
In most programming languages, expensive operations "block the process", which means that any code that is interpreted after an expensive operation will have to wait for said operation to finish before running. An "expensive operation" could be anything from looking up a resource in a database, writing to a file, or fetching some data from an HTTP endpoint.
Here is a basic example in quasi-pseudocode, where we grab some user input, log 1, fetch an item from a database, log 2, log 3, and then show the user the result of the database fetch. Let's just assume that for the sake of this example, that the average time a line of code takes to execute is 1 second, and that our logs operate at that speed, and that we're using those log calls to count time in seconds (which is definitely not the right way to do it, but bare with me here).
Code
orderID = prompt("Please enter an order ID to see it's associated product")


try

  log(1)

  order = ordersDB.query('SELECT * FROM orders WHERE id = ' + orderID)

  log(2)

  log(3)

  print(order)

catch e

  print('error: ' + e)
If we had to actually run this code, we would expect (based on our assumption) that log(1) would run for a second, then the next line would run, and then log(2) would run while the previous line did it's thing and then log(3) would run for a second (making 3 seconds).
In actuality, the database operation could take any set number of seconds to operate, and log(2) would have to wait for this operation to finish executing before it will be run, making our timer incorrect.
If you've been paying attention, you might notice that the log calls have absolutely nothing to do with the database operation, and thus do not have to rely on it executing in order to function on their own, making the above code incredibly inefficient.
This is where asynchronous programming steps in to save the day.
Before we continue, please make note of the try/catch block, most notably the number of times we listen for an error (that's one time, in case you're hungover). Make a mental note of it, put it aside, and we'll come to why you just did that later.
How does asynchronous code work?
In the vast majority of programming languages, asynchronous code is run by the spawning of multiple threads. A program receives some input, and delegates one task to one thread, and another task to another thread, and so on, for a set number of tasks. These threads run these tasks in parallel, and when the thread finishes executing, the value is returned to the main thread. This is a process that is largely similar in concept to multithreading, but it's important to remember that multithreading and asynchronism are not the same thing. This diagram should help illustrate the flow of this process in the context of our order/timer example:
The difference between regular synchronous code and asynchronous code is best explained as a metaphor. Try to imagine that your program is a fancy bistro restaurant. The synchronous version of your restaurant would have one server behind a counter, who is able to serve one customer at a time. Customers would line up in single file, and have to wait for the orders to be processed, calculated and paid for before they can be received. An asynchronous restaurant would have waiters attending multiple customers at a time, the customer makes their order, the waiter adds the order to the system, while the order is being prepared the waiter will go ahead and service some other tables. It's kind of like saying to your program, "Please process these tasks for me - in the meantime I'm going to calculate Pi to the n^th dividend of Fibonacci after the first Prime Roman numeral - when you're done doing your thing, notify me of your findings."
[img]http://t3.gstatic.com/images?q=tbn:ANd9GcQLvxyoe9B_PWv4kCfasaQEorgWYlOGGmmDWrPCRQq4KKjVS5KBXw[/img]
This presents an issue in JavaScript, because JavaScript is not one of the vast majority of languages that runs on multiple threads - it is a single threaded language. So how do we handle asynchronous code in JavaScript?
How asynchronous code works in the context of JavaScript
Let me, for illustrative purposes, show you a function you might already know about:
Code
setTimeout(function() {


}, 500);
If you've done much programming in JavaScript, you might know that this little guy runs whatever is inside that anonymous function body after a specified delay in milliseconds. However, there is something about him that is not very obvious at first glance. Have a look at this code, and try to guess the order in which the console.log statements occur:
Code
setTimeout(function() {

  console.log(1);

}, 0);

console.log(2);
If you guessed that the log statements would output 1, followed by 2, then you are wrong.
So, what's the deal here? Why is this program executing backwards? There's no delay - so it should run in order, right?
Wrong. Function calls cost execution time too, so the whole setTimeout operation was a little bit more costly in terms of processing time than the regular console.log, but that isn't really important - what is important is that the code that followed the setTimeout continued to execute regardless of whether or not the setTimeout was finished.
This is probably due to the native code behind the setTimeout being asynchronous to some degree, and knowing every exact detail of what occurs behind the scenes is not super important - but it gives us something to work with. We can leverage setTimeout to develop asynchronous methods.
Before we get started building an asynchronous method, it's important to first understand how asynchronous methods are consumed at the most basic level.
How to consume asynchronous methods in JavaScript
There are three different basic styles. First off is the callback, errback approach - probably the most common and oldest of the three:
Code
doSomethingAsynchronously(function onSuccess(value) {


}, function onError(error) {


});
You call a function, and pass two functions as arguments to this function. The first function is the "callback", and the second function is the "errback". The callback receives the returned value of the function as a parameter, and is called with this value if no errors occur. If an error does occur, the errback is called instead of the callback, and it usually receives an error message or error object as a parameter.
Second is the success / fail object approach, which you might recognise from something like jQuery's $.ajax method:
Code
doSomethingAsynchronously({

  success: function(value) {


  },

  fail: function(error) {


  }

});
This works almost the same way as the callback / errback approach, the difference being that the object's fail and success methods are called instead - but it does allow for a little more flexibility, for example the method might support more handlers that are called at different steps of execution, like an onProgress: function(percent) {} for a file upload.
The third approach, and probably the most prolific of the three, is the regular callback approach, made popular by Node.js:
Code
doSomethingAsynchronously(function(error, value) {


});
In this approach, the callback is called with an error if one occurs. If not, the first argument is passed as null and the second argument is the resolved value of the method.
Please note that these callbacks may have more than just one parameter, and the most important quality of a callback is that it has access to the scope of the function that it is an argument of.
We'll focus on the third approach when building our asynchronous method.
Building an asynchronous method in JavaScript
Let's use everything we've spoken about up until this point to build a little asynchronous method.
We'll be building a tiny little find method that finds a person in an in-memory database of persons. Our "in-memory database" will simply be an array of people:
Code
var people = [{

  name: 'Kenichi Shirahama',

  occupation: 'History\'s Strongest Disciple',

  school: 'Ryōzanpaku Mixed Martial Arts Dojo'

}, {

  name: 'Ganta "Woodpecker" Igarashi',

  occupation: 'Death Row Inmate',

  school: 'Deadman Wonderland'

}, {

  name: 'Kazuto "Kirito" Kirigaya',

  occupation: 'Professional Gamer',

  school: 'unknown'

}];
Now, let's build an asynchronous method for finding a single person in this array by their name.
We know that our method should accept a name for finding the person, and a callback function that should be called with the found person, or an error if one occurs.
Let's get the basics in place first.
Code
function find(name, callback) {


}
Inside this function, we should define another function, thereby creating a closure, that can be called in a setTimeout.
Code
function find(name, callback) {

  // inner closure

  function lookUpPersonInPeople() {


  }

}
The final part of the basic structure is to actually call this inner function in a setTimeout. We'll give this a delay of 3 seconds to emulate an expensive database operation, just for the sake of example. In best practice, the delay should always be 0.
Code
function find(name, callback) {

  // inner closure

  function lookUpPersonInPeople() {


  }

  // simulate expensive operation with 3 second delay

  setTimeout(lookUpPersonInPeople, 3000);

}
Right now, our code doesn't exactly do anything except call an empty function after a 3 second delay, so we'll implement the part that actually finds the person. Just to make it a little simple, we'll do this using functional programming methods. In EcmaScript 5, arrays have prototypical methods like map, forEach and some.
You're most likely already familiar with forEach if you're reading up on asynchronous programming patterns, but might not be familiar with some. some is exactly the same as forEach, with the tiny exception that it immediately stops iterating when it encounters a callback that returns true.
So, we will define a foundPerson flag as null at the outermost scope of our closure, and we will use this flag to detect if the user has been found when the iteration is complete. Before we focus on errors though, we will just implement the logic that iterates through the people array, returns true when a matching person is found, sets the foundPerson flag to the found person, then calls the callback with the found person.
Keep in mind that the first argument to callback is error, so we'll pass null for that if we've found a person.
Code
function find(name, callback) {

  // flag for the to-be-found person

  var foundPerson = false;

  // inner closure

  function lookUpPersonInPeople() {

    // iterate through each person in people

    people.some(function(person) {

      // if the names match, we've found our target

      if (person.name === name) {

      // set the flag

      foundPerson = person;

      // stop iterating

      return true;

      }

    });

    // call the callback if the person was found

    if (foundPerson) {

      callback(null, foundPerson);

    }

  }

  // simulate expensive operation with 3 second delay

  setTimeout(lookUpPersonInPeople, 3000);

}
Now we finally need to implement error handling - which is actually pretty simple. We just check to see if the foundPerson flag is still null, and if so, create an error and call the callback with the error.
Code
function find(name, callback) {

  // flag for the to-be-found person

  var foundPerson = false;

  // inner closure

  function lookUpPersonInPeople() {

    // iterate through each person in people

    people.some(function(person) {

      // if the names match, we've found our target

      if (person.name === name) {

      // set the flag

      foundPerson = person;

      // stop iterating

      return true;

      }

    });

    // call the callback if the person was found

    if (foundPerson) {

      callback(null, foundPerson);

    } else {

      // call the callback with an error if no person was found

      callback(new Error('Could not find person with name: ' + name));

    }

  }

  // simulate expensive operation with 3 second delay

  setTimeout(lookUpPersonInPeople, 3000);

}
Phew, that was quite a bit of code for such a simple task. But now we can use this method to find a person by their name:
Code
find('Kenichi Shirahama', function(error, person) {

  if (!error) {

    console.log(person.name + ' is ' + person.occupation + ' at ' + person.school);

  } else {

    console.error(error);

  }

});
Let's try that again, but this time with a name that we know does not exist:
Code
find('Subject 404', function(error, person) {

  if (!error) {

    console.log(person.name + ' is ' + person.occupation + ' at ' + person.school);

  } else {

    console.error(error);

  }

});
How to Be a Slave and Build your own Great Pyramids (or: callback hell and why it's a horrible place full of plague and famine)
If you're the type of person who can predict the future, you might have noticed that you might end up in a particularly bad situation with this code structure (well, that or you've realised you can use your psychic future seeing abilities to make money much easier than by programming and are probably fantasising about being on a cruise somewhere in the Caribbean).
If you're not that type of person, your future-seeing brethren definitely have reason to worry, and so should you.
What do you think will happen if you use many of these asynchronous methods in sequence? Let me illustrate by reading a directory of files, iterating through these filenames, reading in the files individually and uploading them to some random endpoint:
Code
var fs = require('fs');

var request = require('request');


fs.readdir('./images', function(error, files) {

  if (error) {

    throw error;

  } else {

    files.forEach(function(file) {

      fs.readFile(file, function(error, file) {

      request.post('http://some.random/endpoint', file, function(error, response) {

      if (error) {

            throw error;

      } else {

            console.log('File ' + file.path + ' uploaded.');

      }

      });

      });

    });

  }

});
Now imagine you wanted to do other stuff with that response, like save it to a dictionary database of image paths to result URLs, and then produce a document of that dictionary and asynchronously send it to another API that prints the document from a fax machine somewhere in the Swiss Alps... you'd be getting in pretty deep, having to nest deeper with each method and check for that error all the time. It could become quite unsettling. The huge sideways pyramid of whitespace on the left created by all this nesting is called the pyramid of doom, and when you see it, it is the landmark that tells you that you are in callback hell. Be sure to send postcards, if you can find them.
Another issue with this, though not immediately obvious, are all the anonymous functions. If errors throw, you'll lose the execution context of those errors and your stack trace will be littered with <anonymous>.fn tokens. Identifying where your errors occur will be tough.
All of this combines and results in extremely unreadable, hard-to-understand code.
Luckily for your fortunate-unfortunate self, there is an escape route.
How to Escape Callback Hell
Use CoffeeScript. Just kidding. But this does raise a valid point, a lot of programmers new to the JS space think using a language like CoffeeScript might help solve the problem by reducing the amount needed to type because of the terse syntax it provides, kind of like a trade of some form of productivity for another form of productivity.
Code
fs = require 'fs'

request = require 'request'


fs.readdir './images', (error, files) ->

  if error then throw error

  files.forEach (file) ->

    fs.readFile file, (error, file) ->

      if error then throw error

      request.post 'http://some.random/endpoint', file, (error, response) ->

      if error then throw error

      console.log "File #{file.path} uploaded."
The reality of the matter is that using CoffeeScript does not directly solve the problem here. While it does add some benefit by removing some of the syntax, it doesn't exactly mitigate the need to constantly check for errors and it does not get rid of the need to nest, it also adds no benefit to that anonymous function issue - but it does get rid of half of that pyramid of doom, which is nice and all, but you're still left with half a pyramid of doom. Whether you have a whole turd or half a turd, it's still a turd, and you have it. Congratulations - here, have a Noddy badge. You deserve this for your achievement. Put it in your trophy room, right next to your shiny half-turd:
disclaimer: Possible bias. I'm actually rather fond of CoffeeScript. But it does not solve everything.
Getting Rid of Anonymous Functions
Here's something we can do without much thought that can help ease the debugging, and that's by giving our anonymous functions some identifiable names:
Code
var fs = require('fs');

var request = require('request');


fs.readdir('./images', function readFiles(error, files) {

  if (error) {

    throw error;

  } else {

    files.forEach(function iterateFiles(file) {

      fs.readFile(file, function readFile(error, file) {

      request.post('http://some.random/endpoint', file, function uploadFile(error, response) {

      if (error) {

            throw error;

      } else {

            console.log('File ' + file.path + ' uploaded.');

      }

      });

      });

    });

  }

});
Hoisting to the Rescue!
The above code has one immediately obvious benefit to it's predecessor, and that is that it will now display actual function names rather than <anonymous>.fn tokens in the error stack. This makes debugging easier. But there is one other benefit that is not immediately obvious, and it comes into practice when we remember that JavaScript "hoists" function definitions to the top of the scope at execution time. We can define our functions outside of where they are called for some very readable code:
Code
var fs = require('fs');

var request = require('request');


fs.readdir('./images', readFiles);


function readFiles(error, files) {

  if (error) throw error;

  files.forEach(iterateFiles);

}


function iterateFiles(file) {

  fs.readFile(file, readFile);

}


function readFile(error, file) {

  if (error) throw error;

  request.post('http://some.random/endpoint', file, uploadFile);

}


function uploadFile(error, response) {

  if (error) throw error;

  console.log('File ' + file.path + ' uploaded.');

}
This gets rid of most of our issues by trading in just a little bit more verbosity. But we still have to check for errors in multiple places. Though this may not be perfect, it is at least readable and much easier to understand. Plus, there's no pyramid of doom. Yay!
We can improve this a little further and make errors a lot easier to handle.
All Hail The Mighty EventEmitter
In Node.js, asynchronous methods work a little differently under the hood than I explained above. You might have heard about the mysterious "event loop" that is behind every Node program. Pretty much everything in Node emits events behind the scenes that get queued in this loop, and some methods add listeners for certain events that call methods when those events emit. Which is kind of like what we did above, just a different, more systemised architecture.
(side note: Node.js also prefers setImmediate and nextTick as opposed to setTimeout, which work similarly)
We have access to the class that emits these events in Node, and we can use it to make our error handling a little easier. It's quite simple:
Code
var EventEmitter = require('events').EventEmitter;

var fs = require('fs');

var request = require('request');


var emitter = new EventEmitter();


fs.readdir('./images', readFiles);


function readFiles(error, files) {

  if (error) emitter.emit('error', error);

  files.forEach(iterateFiles);

}


function iterateFiles(file) {

  fs.readFile(file, readFile);

}


function readFile(error, file) {

  if (error) emitter.emit('error', error);

  request.post('http://some.random/endpoint', file, uploadFile);

}


function uploadFile(error, response) {

  if (error) emitter.emit('error', error);

  console.log('File ' + file.path + ' uploaded.');

}
We haven't changed much, and we still have to check for errors in multiple places, but this is a big improvement, because if we want to do anything with those errors, we only have to do it in one place:
Code
emitter.on('error', function(error) {

  // handle the error in here

});
This code is still a little bit haphazard. Perhaps it might be worth representing as a singleton object that inherits from EventEmitter. While we're doing that, we might as well change up the API a little bit and make it easy to perform this logic on any directory of files. I'm not going to delve into the process here, so this is what that looks like:
Code
// we use this for quick hasOwnProperty checks

var __hasProp = {}.hasOwnProperty;


// this makes `child` inherit everything from `parent`

var __extends = function(child, parent) {

  for (var key in parent) {

    if (__hasProp.call(parent, key)) child[key] = parent[key];

  }

  function ctor() {

    this.constructor = child;

  }

  ctor.prototype = parent.prototype;

  child.prototype = new ctor();

  child.__super__ = parent.prototype;

  return child;

};


var fs = require('fs');

var request = require('request');

var EventEmitter = require('events').EventEmitter;


// create a cosntructor, passing EventEmitter as the superconstructor

FileUploader = (function(_super) {

  // this extends the superconstructor

  __extends(FileUploader, _super);


  function FileUploader() {

    // binds the correct context for the superconstructor methods to work

    return FileUploader.__super__.constructor.apply(this, arguments);

  }


  FileUploader.prototype.uploadFilesInDirectory = function(directory) {

    return fs.readdir(directory, this.iterateFiles);

  };


  FileUploader.prototype.iterateFiles = function(error, files) {

    if (error) {

      this.emit('error', error);

    }

    return files.forEach(this.readFile);

  };


  FileUploader.prototype.readFile = function(file) {

    return fs.readFile(file, this.uploadFile);

  };


  FileUploader.prototype.uploadFile = function(error, file) {

    if (error) {

      this.emit('error', error);

    }

    return request.post('http://some.random/endpoint', file, this.onUpload);

  };


  FileUploader.prototype.onUpload = function(error, file) {

    if (error) {

      this.emit('error', error);

    }

    return console.log("File " + file.path + " uploaded.");

  };


  return FileUploader;


})(EventEmitter);
Just for the sake of interest, here is what the exact same code looks like in CoffeeScript:
Code
fs             = require 'fs'

request      = require 'request'

{EventEmitter} = require 'events'


class FileUploader extends EventEmitter


  uploadFilesInDirectory: (directory) ->

    fs.readdir directory, @iterateFiles


  iterateFiles: (error, files) ->

    if error then @emit('error', error)

    files.forEach @readFile


  readFile: (file) ->

    fs.readFile file, @uploadFile


  uploadFile: (error, file) ->

    if error then @emit('error', error)

    request.post 'http://some.random/endpoint', file, @onUpload


  onUpload: (error, file) ->

    if error then @emit('error', error)

    console.log "File #{file.path} uploaded."
Now, we can use this little program to upload any directory we want, and handle errors rather easily:
Code
var uploader = new FileUploader();

uploader.on('error', function handleError(error) {

  // do something with error

});

uploader.uploadFilesInDirectory('./images');
Promises
Earlier, we created this really intrinsic constructor API for dealing with readable, asynchronous code that allowed you to handle errors in one place.
Now let me show you just how much of a waste of time that was with this snippet of code that does the exact same thing:
Code
var when = require('when');

var node = require('when/node');

var fs = require('fs');

var request = require('request');


when.map(node.call(fs.readdir, './images'), function fileHandler(file) {

  return node.call(fs.readFile, file.path)

    .then(function uploadFile(file) {

      return node.call(request.post, 'http://some.random/endpoint', file);

    })

    .then(function onResponse(response) {

      console.log(response);

    });

})

  .catch(function errorHandler(error) {

    // do something with the error

  });
The when variable here is a reference to the when.js promise library, which gives us the when.map and node.call methods. when.map resolves an array of values or an array of promises for values. If any of these values throw an error, our error handler will catch it. when.map accepts a predicate function that has access to the resolved values in our array of promises returned by fs.readdir. node.call simply creates a promise for the result of a node-style callback. If any of the methods we promisified using node.call throw errors, those errors will bubble up to our error handler, where we can then handle them.
If you inspect the code closely, you might notice that this is modelled as closely to the try / catch block pattern as possible (well, to the extent that asynchronous JavaScript can provide, anyway).
I'm not going to delve too much into promises here, because there are plenty of tutorials and even a standardised specification called "Promises/A+" that you can learn from if you Google around for a bit.
The only thing you really need to know about promises for now is that they are just objects and can be passed around just as easily as any function. Well, that's the premise behind them anyway.
The specific name for a promise is a "deferred object" - a deferred object has three states: pending, resolved and rejected. When a promise is busy executing, it is pending. When a promise succeeds, it resolves with a value. If it fails, it rejects with an error. A promise will return a "thenable", which is another object that is essentially just a chainable API for accessing these resolved values or rejection errors, that always has a "then" method.
This is what a promise constructor might look like on top of our asynchronous find method from earlier:
Code
var when = require('when');

function findPromise(name) {

  var deferred = when.defer();

  find(name, function(error, person) {

    if (error) {

      deferred.reject(error);

    } else {

      deferred.resolve(person);

    }

  });

  return deferred.promise;

}


findPromise('Kenichi Shirahama')

  .then(function(person) {

    // ...

  })

  .catch(function (error) {

    // ...

  });
The Future of Asynchronous JavaScript (is actually now)
In ES6, we can use promises in a much more descriptive manner that might make you smile if you are used to writing synchronous code, using generator functions:
Code
let when = require('when');

let node = require('when/node');

let generator = require('when/generator');

let fs = require('fs');

when.map(node.call(fs.readdir, './images'), generator.lift(function*(image) {

  try {

    let file = yield node.call(fs.readFile, image.path);

    let uploadResult = yield node.call(request, 'http://some.random/endpoint', file);

    console.log('File ' + file.path + ' uploaded to ' + uploadResult.url);

  } catch (error) {

    // do something with error

  }

}));
You can use this method of asynchronous programming today by using an ES6-ES5 transpiler like Google's Traceur Compiler or just directly in the latest Node.js pre-release.
ES7 has plans for async/await keywords, which essentially just hides promises behind the scenes. So things are definitely looking up for JavaScript.
Ending note:
I know I never covered promises as thoroughly as one might expect from such an article, but in truth they are quite complex to understand to a beginner, and I am not 100% confident in my ability to teach them as a concept without making mistakes. If you do not understand promises, do not be alarmed - we all went through this at some stage. The best way to improve your promise skills is simply to just dive in and code something with them. Perhaps starting with an easier library like Q.js might be worth a try. On that note, there are hundreds of articles that will teach you about promises - just be sure to make certain that the promise implementation you are using is Promises/A+ compliant.


